Context
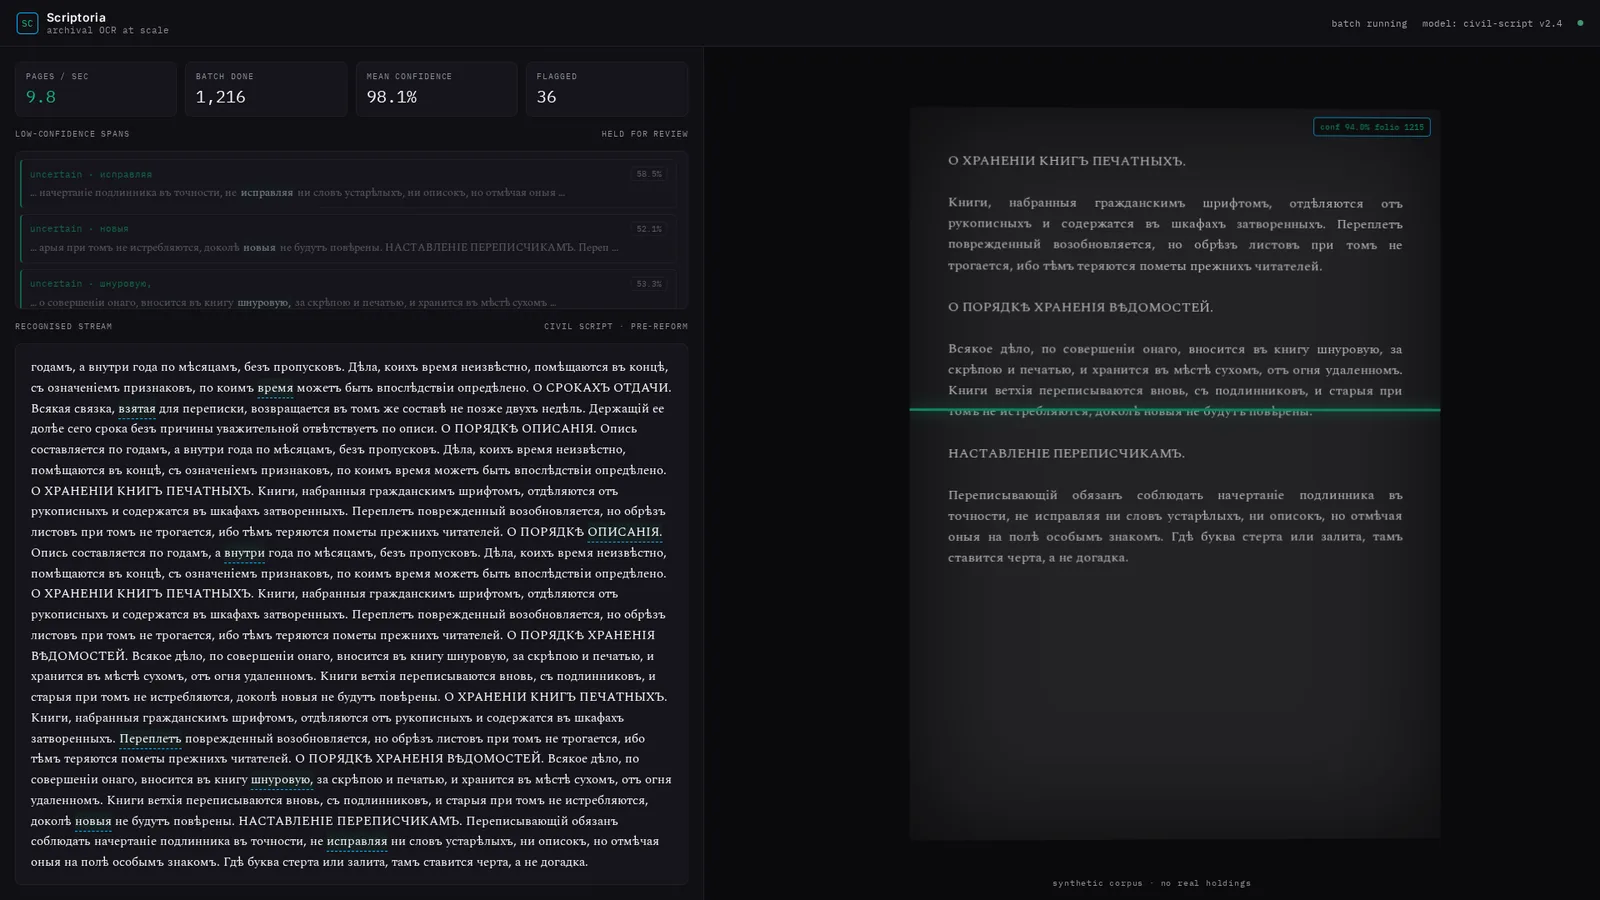
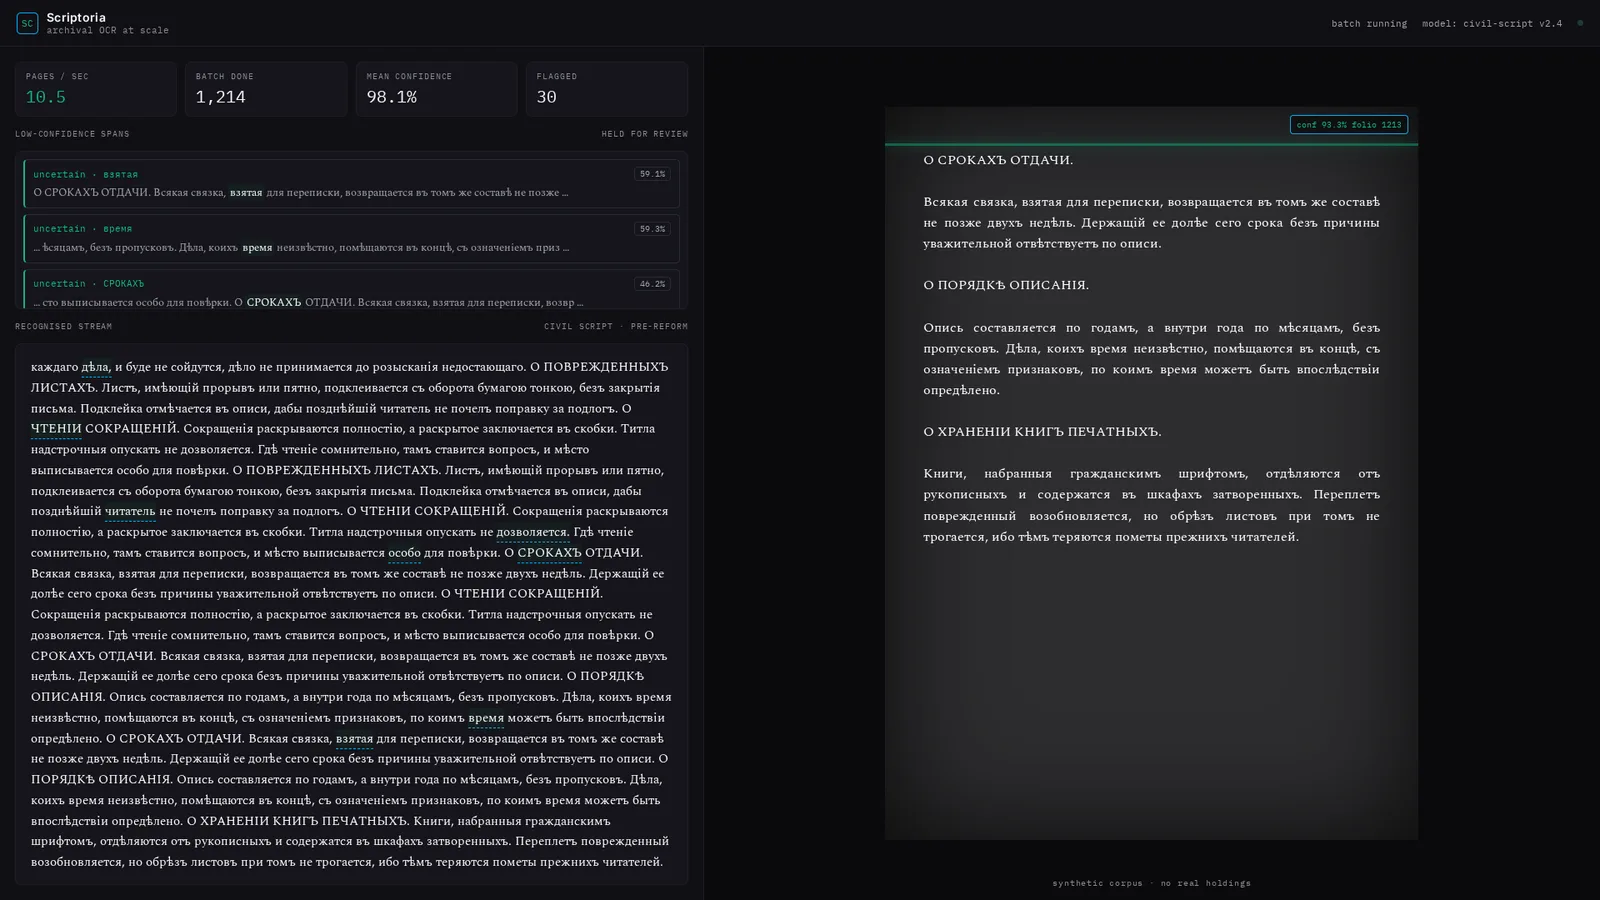
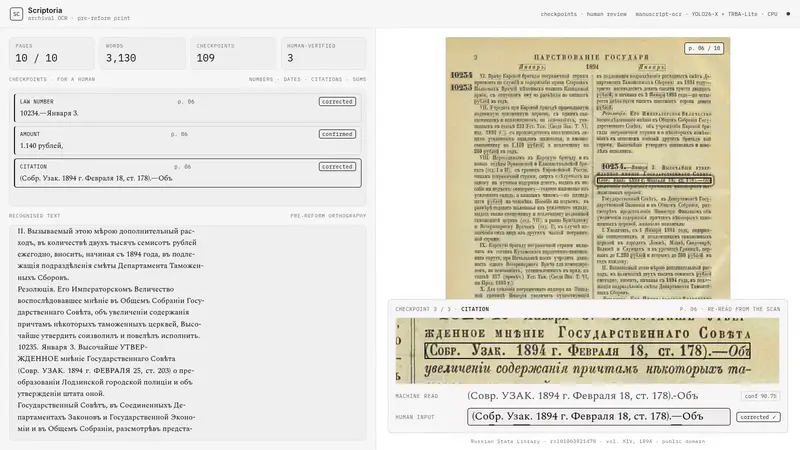
Pre-reform print (ѣ, і, ъ) in two columns: the library's own text layer breaks words apart and mixes the columns, so it can't be searched.
Task
Put archive recognition on a conveyor and leave to a human what carries the document's meaning.
Approach
manuscript-ocr on a CPU: a YOLO26-X detector and a TRBA-Lite recogniser with the pre-reform alphabet, plus a column-aware reading order. Checkpoints — law numbers, dates, citations of the Collection of Statutes, sums — go to a human, who re-reads the scan and types the value.
Result
The first 10 pages of the Complete Collection of Laws, vol. XIV, 1894 (Russian State Library): 3,130 words in about 2.5 minutes on a CPU. Searchable text in the original orthography; the checkpoints verified by a human.